- Format-3
- Curiosity
- Perspective
- Cloud Cost Optimization Is a Product Metric, Not an Ops Cleanup
Cloud Cost Optimization Is a Product Metric, Not an Ops Cleanup
Share article
{
"@graph": [
{
"@type": "Article",
"image": {
"url": "https://media.babylovegrowth.ai/blog-images/organization-13731/1791981833529_Product-engineering-and-finance-review-cloud-costs.jpeg",
"@type": "ImageObject",
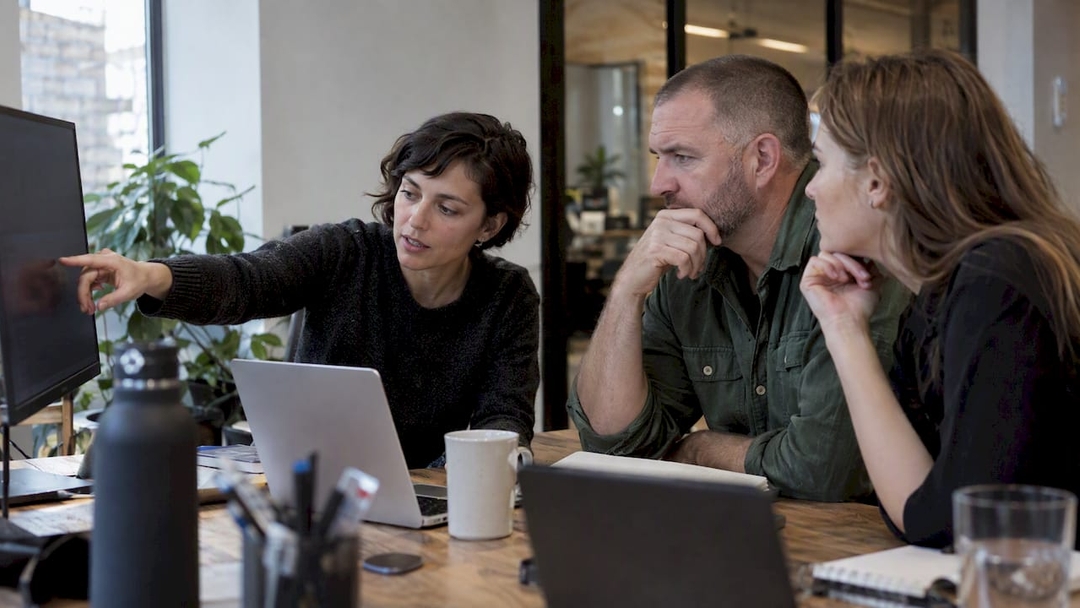
"caption": "Product, engineering, and finance review cloud costs"
},
"author": {
"url": "https://format-3.co",
"name": "Format-3",
"@type": "Organization"
},
"headline": "Cloud Cost Optimization Is a Product Metric, Not an Ops Cleanup",
"publisher": {
"url": "https://format-3.co",
"name": "Format-3",
"@type": "Organization"
},
"inLanguage": "en-GB",
"description": "See how FinOps teams cut cloud waste, control AI and LLM spend, and make cost a product delivery metric with a repeatable 90 day roadmap.",
"dateModified": "2026-10-14T12:48:11.926Z",
"datePublished": "2026-10-14T12:48:11.926Z"
},
{
"@type": "BreadcrumbList",
"itemListElement": [
{
"item": "https://format-3.co",
"name": "Format-3",
"@type": "ListItem",
"position": 1
},
{
"item": "https://format-3.co/cloud-cost-optimization",
"name": "Cloud Cost Optimization Is a Product Metric, Not an Ops Cleanup",
"@type": "ListItem",
"position": 2
}
]
}
],
"@context": "https://schema.org"
}
Cloud Cost Optimization Is a Product Metric, Not an Ops Cleanup
Cloud cost optimisation is the practice of aligning cloud spend with business value. Rightsizing, removing idle resources, tiering storage, buying commitments only where usage justifies them and enforcing tag-backed ownership deliver most of the early savings. Lasting results, though, come from a FinOps operating model and a decision metric you measure every week.
TL;DR:
Format-3
Build Products With Cost in Mind
Format-3 brings strategy, design, engineering, and growth together to create and scale digital products around business needs.
Table of Contents
Which tactics cut cloud spend without hurting performance?
How do you build a FinOps operating model that repeats?
How do you optimise AI and LLM costs?
What should you look for in cost management tools?
Which KPIs prove that cost optimisation is working?
What does a 90-day cloud cost optimisation roadmap look like?
How do you attribute cloud costs and run chargeback fairly?
What governance and compliance rules shape your cost decisions?
How do you keep the savings from fading?
Why cost belongs in product thinking, not just operations
Want a partner to build cost-aware products with you?
FAQ
Sources
Which tactics cut cloud spend without hurting performance?
Start where the waste is obvious and the risk is low. Cloud provider guidance, such as Azure’s cost management pages, points to the same short list: shut down unused resources, rightsize, and use savings plans for steady compute. None of it is glamorous. All of it is consistently skipped, because nobody owns the bill.
Treat the work as two tracks. Quick wins need no architectural debate. Programme work needs organisational muscle. Confusing the two is how teams plan a commitment strategy while orphaned volumes quietly keep generating costs.
Here is the prioritised playbook:
- Rightsize compute, containers and databases. Use p95 and p99 performance guardrails, not averages. An average hides the spike that pages someone at 3 a.m., and a resize that ignores peak load is a regression with a discount attached.
- Remove idle and unattached resources. Orphaned volumes, forgotten snapshots, unassociated IP addresses and idle virtual machines accumulate silently. A weekly sweep with an owner attached beats a heroic annual clean-up.
- Auto-shutdown non-production. Development and staging environments rarely need to run overnight or at weekends. Scheduled power-down is among the cheapest changes you can make, and it also forces a healthy question: why does this environment exist?
- Apply storage lifecycle policies. Move cold data to lower-cost tiers automatically and expire what has no retention requirement. Data that nobody reads should not be priced as if everybody does.
- Model commitments before you buy them. Reservations and savings plans reward predictability and punish optimism. Simulate coverage against your actual utilisation history, and commit only to the baseline you are confident will still exist next year.
- Enforce tagging at deploy time. Spend you cannot allocate is spend you cannot optimise. Make ownership tags a precondition of deployment rather than a clean-up exercise afterwards.
Quick wins versus programme work
Quick wins are the orphan volumes, idle machines and always-on test environments. Programme work is commitment planning, tagging backfill for legacy estates and re-architecting workloads that scale poorly. Run both at once, but report them separately. Mixing them makes the programme look slow and the quick wins look trivial, and both impressions are wrong.
The sequencing matters more than most teams admit. Rightsizing before you commit is not a tip, it is arithmetic: commit to an oversized footprint and you lock in waste, with a discount that makes it feel prudent.
Why guardrails beat heroics
A rightsizing recommendation without performance context is a guess. Pair every change with a rollback path and a defined observation window, and treat latency and error budgets as constraints the saving must respect. Cost optimisation that quietly degrades the product is not optimisation. It is a deferred incident.
Pro Tip: Before touching instances, tag your largest cost drivers with named owners. The conversation changes once people, not departments, are attached to line items.
The pressure to do this well is only increasing. Gartner forecasts continued growth in worldwide public cloud end-user spending, which means every inefficiency you tolerate today compounds as budgets scale. Waste is not a fixed tax. It grows with you.
There is a quieter lesson in all of this. The levers above are well known, yet most organisations still leave them half-pulled. The constraint is rarely knowledge. It is ownership, cadence and the willingness to make cost a standing agenda item rather than a quarterly panic.
How do you build a FinOps operating model that repeats?
Tactics decay without structure. The savings you win can evaporate unless someone owns the next cycle. A FinOps operating model is the structure that makes optimisation a habit rather than a project.
The FinOps Foundation’s 2026 framework updates recommend defining Scopes, which are segments of spend mapped to a product or cost centre, so that FinOps activity connects to business strategy. That framing is quietly radical. It moves the conversation from “the cloud bill is too high” to “this product’s margin is eroding”, and only the second sentence gets an executive’s attention.
Here is how we would set it up, in order:
- Define Scopes mapped to product or cost centre. A Scope is a slice of spend that one accountable owner can reason about. Start with your largest two or three products rather than attempting to model the whole estate on day one.
- Assign a single owner per Scope. Shared ownership is no ownership. Engineering owns efficiency, finance owns forecasting and planning, and product owns the trade-off between cost and customer value. One named person arbitrates when those pull apart.
- Ingest billing data daily and normalise it. Pull invoices and usage from every provider, reconcile their differing vocabularies into one schema, and attach CMDB and tag metadata so each line can be allocated to a Scope.
- Automate the routing. Anomalies should flow to the owner of the affected Scope, and policy violations should open tickets in the system engineers already use. A dashboard nobody opens is not governance.
- Feed allocation into planning. Use attributed spend to drive forecasts, commitment purchases and budgets, so that finance stops negotiating with an undifferentiated total.
The three roles that make it work
Engineering needs the authority to change resources, finance needs trustworthy allocation to forecast against, and product needs visibility of unit costs to decide what is worth building. The FinOps Framework organises this around understanding usage and cost, quantifying business value, and optimising usage and cost. We find it useful as a checklist of what must exist, not as a doctrine to adopt wholesale.
The State of FinOps report shows that workload optimisation and waste reduction remain top priorities, and that many practitioners are widening their remit to SaaS and other scopes. That expansion is a signal worth heeding: the discipline is migrating from “cloud bill hygiene” to “technology value management”. Teams that wait to be asked will find the remit assigned to someone else.
One last point on the model. Resist the urge to centralise everything in a FinOps team. Central enablement is valuable, and the core FinOps principles stress collaboration and timely, accessible data. But a central team that does the optimising for everyone has built a bottleneck with a budget. The job is to make engineers capable and informed, not to take the pager from them.
How do you optimise AI and LLM costs?
General cloud guides stop at instances and storage. AI spend behaves differently, and applying instance-hour thinking to it produces confident, wrong decisions.
The core difference is the billing unit. Traditional infrastructure is billed on capacity over time: you pay for the instance-hour whether it is busy or idle. LLM workloads are largely billed on tokens and inferences, so cost tracks what your application sends and receives. LLM token pricing typically distinguishes input from output, and the two are rarely priced equally. A verbose prompt and a chatty response are both line items.
That changes the decision metric. Cost per instance tells you almost nothing about whether an AI feature is worth running. The metric that matters is cost per successful output: what you spend to get one answer that actually solves the user’s problem. Everything else is diagnostic, including cost per inference, cost per token and cache hit rate. A cheap model that fails often can cost more per success than an expensive one that rarely does.
The levers are mostly engineering decisions rather than procurement ones:
- Trim tokens. Strip redundant context, compress system prompts and send only what the model needs. Prompt bloat is the AI equivalent of an oversized instance.
- Cap output length. Set sensible maximums so a runaway response does not become a runaway invoice.
- Cache aggressively. Repeated or near-repeated requests should not pay full price twice. Track your cache hit rate as a first-class number.
- Route by difficulty. Send simple requests to smaller, cheaper models and reserve the large model for tasks that genuinely need it.
- Separate batch from interactive. Work that can wait should not occupy low-latency, premium capacity.
- Manage provisioned throughput deliberately. Reserved capacity rewards steady demand and punishes idle headroom, exactly like compute commitments.
For attribution, we recommend a gateway or proxy in front of your model calls. It records every request with its owner, feature and token counts, without invasive changes to each application. You get request-level attribution almost for free, and routing, caching and caps become policies you set once.
The sequence we follow is measure, attribute, govern. Measure first, because you cannot argue with a bill you cannot decompose.
The spending context is not subtle: Gartner forecasts continued growth in worldwide public cloud end-user spending, and AI workloads are a large part of why the growth is unlikely to slow, so token discipline is cheaper to build now than to retrofit later.
What should you look for in cost management tools?
Tools do not optimise anything on their own. They shorten the distance between a signal and a decision. Judge them by that distance, and judge categories before brands, because the category tells you which problem you are actually buying a solution to.
- Visibility platforms. Look for daily ingestion, bill normalisation across providers and flexible allocation modelling. If a platform cannot attach your tags and CMDB metadata to spend, it will produce attractive charts and no accountability.
- Rightsizing engines. The recommendation matters less than its context. Insist on performance data alongside every suggestion and a clear flag for which changes are safe to automate and which need a human.
- Commitment modelling. The point is to simulate reservation and savings-plan outcomes against real utilisation before you spend. A good model shows coverage, utilisation and the downside if demand shrinks.
- Policy automation. Enforce tagging, region constraints, time-to-live values and auto-power policies at deploy time. Prevention is cheaper than remediation, and nobody enjoys auditing last quarter’s untagged resources.
- Anomaly detection. It should detect deltas quickly, attach ownership metadata and route the alert automatically. An anomaly that lands in a shared inbox is merely an anecdote.
A practical test for any of these: ask what happens to the finding after it appears. If the answer is “someone will see it”, keep looking. The tools worth paying for are the ones that close the loop between detection, owner and action.
Which KPIs prove that cost optimisation is working?
Savings are a result, not a metric. The numbers that tell you whether the system is healthy are those that show whether spend is understood, predictable and efficient.
- Percentage of allocatable spend. How much of the bill maps to an owner? Below that line, every other metric is built on sand.
- Forecast variance. The gap between what finance expected and what arrived. This is the number the CFO feels.
- Commitment utilisation. Are your reservations and savings plans being used, or are you paying for shelfware?
- Waste detected. Idle, unattached and oversized resources, tracked as a trend rather than a one-off audit.
- AI unit metrics. Cost per successful output, cost per inference or token, average input and output tokens, and cache hit rate.
Cadence matters as much as the metrics. Owners should see daily deltas, a weekly anomaly summary should reach the wider group, and monthly commitment forecasts should go to finance and engineering leads together. Then use the numbers for decisions: strong utilisation justifies the next commitment, rising waste justifies a clean-up sprint, and widening forecast variance justifies a harder look at allocation before anyone argues about budgets.
What does a 90-day cloud cost optimisation roadmap look like?
A focused roadmap can produce measurable change while holding attention. Run it as measure, attribute, govern.
- Baseline and quick wins. Inventory what you run, choose a decision metric and baseline it, then remove obvious waste such as orphaned volumes, idle machines and always-on test environments.
- Attribute and optimise. Instrument attribution, apply rightsizing, make commitments where utilisation is stable, and switch on caching and output caps for AI workloads.
- Govern. Automate policy enforcement, publish the KPIs, add anomaly routing and begin structured commitment planning.
Finish with a handoff checklist: every Scope has a named owner, tags are enforced at deploy time, alerts route automatically, and finance receives a monthly forecast built from allocated spend.
Pro Tip: Pick a decision metric early and publish it everywhere. A single number that everyone argues about beats dashboards that nobody reads.
How do you attribute cloud costs and run chargeback fairly?
Attribution answers “who caused this spend”. Chargeback answers “who pays for it”. They are related but not identical, and conflating them is a reliable way to start an internal feud.
Begin with showback: report each team’s allocated cost without moving any money. It builds trust in the data and exposes the awkward cases, such as shared platforms, networking and security tooling that serve everyone, before real budgets are at stake. Only once the allocation survives scrutiny should you consider moving to chargeback, where costs hit a team’s own budget.
The hardest part is shared cost. You have three honest options: split it proportionally to consumption, split it evenly, or hold it centrally as an overhead. Proportional allocation is fairer but needs better data. Even splits are simple but reward heavy users. Whatever you choose, document the rule and apply it consistently, because a fair method that changes every quarter feels arbitrary to the people paying.
Tagging and account structure do the heavy lifting here, which is why we insist on them at deploy time. Untagged spend should land in a visible “unallocated” bucket that someone is accountable for shrinking, not vanish into a general pool. Treat that bucket’s size as a KPI and watch it fall.
What governance and compliance rules shape your cost decisions?
Cost optimisation does not happen in a vacuum, and some of your most expensive choices are not really yours to make. Data residency requirements may fix which regions you can use, retention rules may forbid the aggressive deletion that would otherwise save money, and security controls such as logging and encryption carry their own costs. The cheapest architecture is the one that is also permitted.
Write these constraints down as policy rather than folklore. Region restrictions, mandatory tags, time-to-live defaults for temporary environments and approval thresholds for large purchases can all be enforced at deploy time, which removes the argument and the audit trail problem together. Where a compliance requirement forces a cost, record it as a known, owned expense so it is not mistaken for waste during the next clean-up.
Provide a sanctioned route to exceptions as well. Rigid policy with no escape valve gets bypassed, and bypassed policy is worse than none because it creates the illusion of control. A short, fast exception process keeps engineers inside the system and gives finance visibility of what is being waived and why.
How do you keep the savings from fading?
Most cost programmes fail slowly, not dramatically. An initial drop can be satisfying, but attention moves elsewhere and the bill can quietly return to where it started. The cause is cultural, not technical.
Sustaining the effort means changing what people are rewarded for. If engineers are measured only on shipping speed, cost will always lose. Make efficiency a visible part of how teams are assessed, put each team’s own numbers in front of them regularly, and celebrate the engineer who retired an expensive service as loudly as the one who launched a new one.
Keep the cadence light but unbreakable: a short recurring review per Scope, a clear owner for each action and a public record of what was saved and what it funded. Linking savings to something tangible, such as a feature or a hire, turns cost work from a tax into an investment. Our own view on this echoes the case for collaboration across functions in product development: cost goes down durably when finance, engineering and product share a table, not when one of them issues instructions.
Why cost belongs in product thinking, not just operations
Here is the uncomfortable claim: most cloud waste is not created by operations. It is designed in, long before anything is deployed. A feature built for imaginary scale, an architecture chosen because it was fashionable, a model picked because it was the largest on offer. By the time the invoice arrives, the expensive decision is months old.
That is why we treat cost as a product metric, owned alongside latency and conversion. Discovery work and design sprints exist to kill speculative spend early, before anyone provisions infrastructure to support an idea that customers never wanted. Rework is the most expensive line item nobody tracks. We build with that discipline across our AI product design and development work, and our view on hiring a partner rather than a vendor comes from the same conviction: the cheapest cloud is the one you never needed to run.
— Martin
Want a partner to build cost-aware products with you?
Some teams would rather embed cost discipline into delivery than bolt it on afterwards. That is where we come in. Our work spans:
- Discovery and design sprints that test an idea before it earns infrastructure.
- AI implementations designed around unit cost from the first prototype.
- Engineering delivery.
An engagement can help you build cost discipline into delivery. See what we offer on our services page and tell us where your spend is hardest to explain.
FAQ
What is cloud cost optimisation?
Cloud cost optimisation is the practice of matching cloud spend to the business value it produces. It combines technical changes, such as rightsizing and removing idle resources, with financial and organisational practices, such as allocation, forecasting and ownership. The goal is lower waste, not lower capability.
How can cloud computing reduce costs?
Cloud computing reduces costs by letting you pay for capacity you use rather than owning hardware for peak demand. The saving only materialises if you switch off idle resources, rightsize workloads and commit to steady usage. Cloud provider guidance lists shutting down unused resources, rightsizing and savings plans as practical levers.
How can cloud run reduce costs?
Serverless and container platforms that scale to zero reduce cost by charging only while requests are served, so idle time costs little. You still need sensible concurrency limits, right-sized memory and CPU allocations, and monitoring of request volume. Check your provider’s current billing model before assuming any workload will be cheaper.
What is cost management and optimisation in cloud computing?
Cost management is the ongoing work of understanding, allocating and forecasting cloud spend. Optimisation is the act of reducing waste and improving rates within that picture. The FinOps Framework frames this as understanding usage and cost, quantifying business value, and optimising usage and cost.
How do you reduce LLM costs without hurting quality?
Trim prompts, cap output length, cache repeated requests and route simple tasks to smaller models. Track cost per successful output rather than cost per token alone, so a cheaper but less reliable model does not look better than it is.
Sources
Recommended
More thoughts
Thought leadership creates value, builds knowledge and takes a stand, bridging the gap between traditional and digital platforms
Agent-first brands: Adapting for AI-driven discovery
Discover how agent-first brand strategy is reshaping discovery in technology, healthcare, and entertainment as AI agents become the gatekeepers of purchase decisions.
Driving Growth with Attention, Transparency, and Friction
Discover how our approach helps the team thrive and deliver impactful work.
SayHello!
- 21:25:52NashvilleUSA
- 22:25:52New YorkUSA
- 03:25:52LondonUK
- 04:25:52KatowicePoland
- 04:25:52BratislavaSlovakia
- 05:25:52PlovdivBulgaria
- 06:25:52DubaiUAE